Scene 15 of 26 · Boston
8 questions · nuScenes, DriveLM test split
scene c5b36e5275cc4a2285d095e87347c49a · frame 04de5a1d4f8b45a3a62d6bf0ee07c715
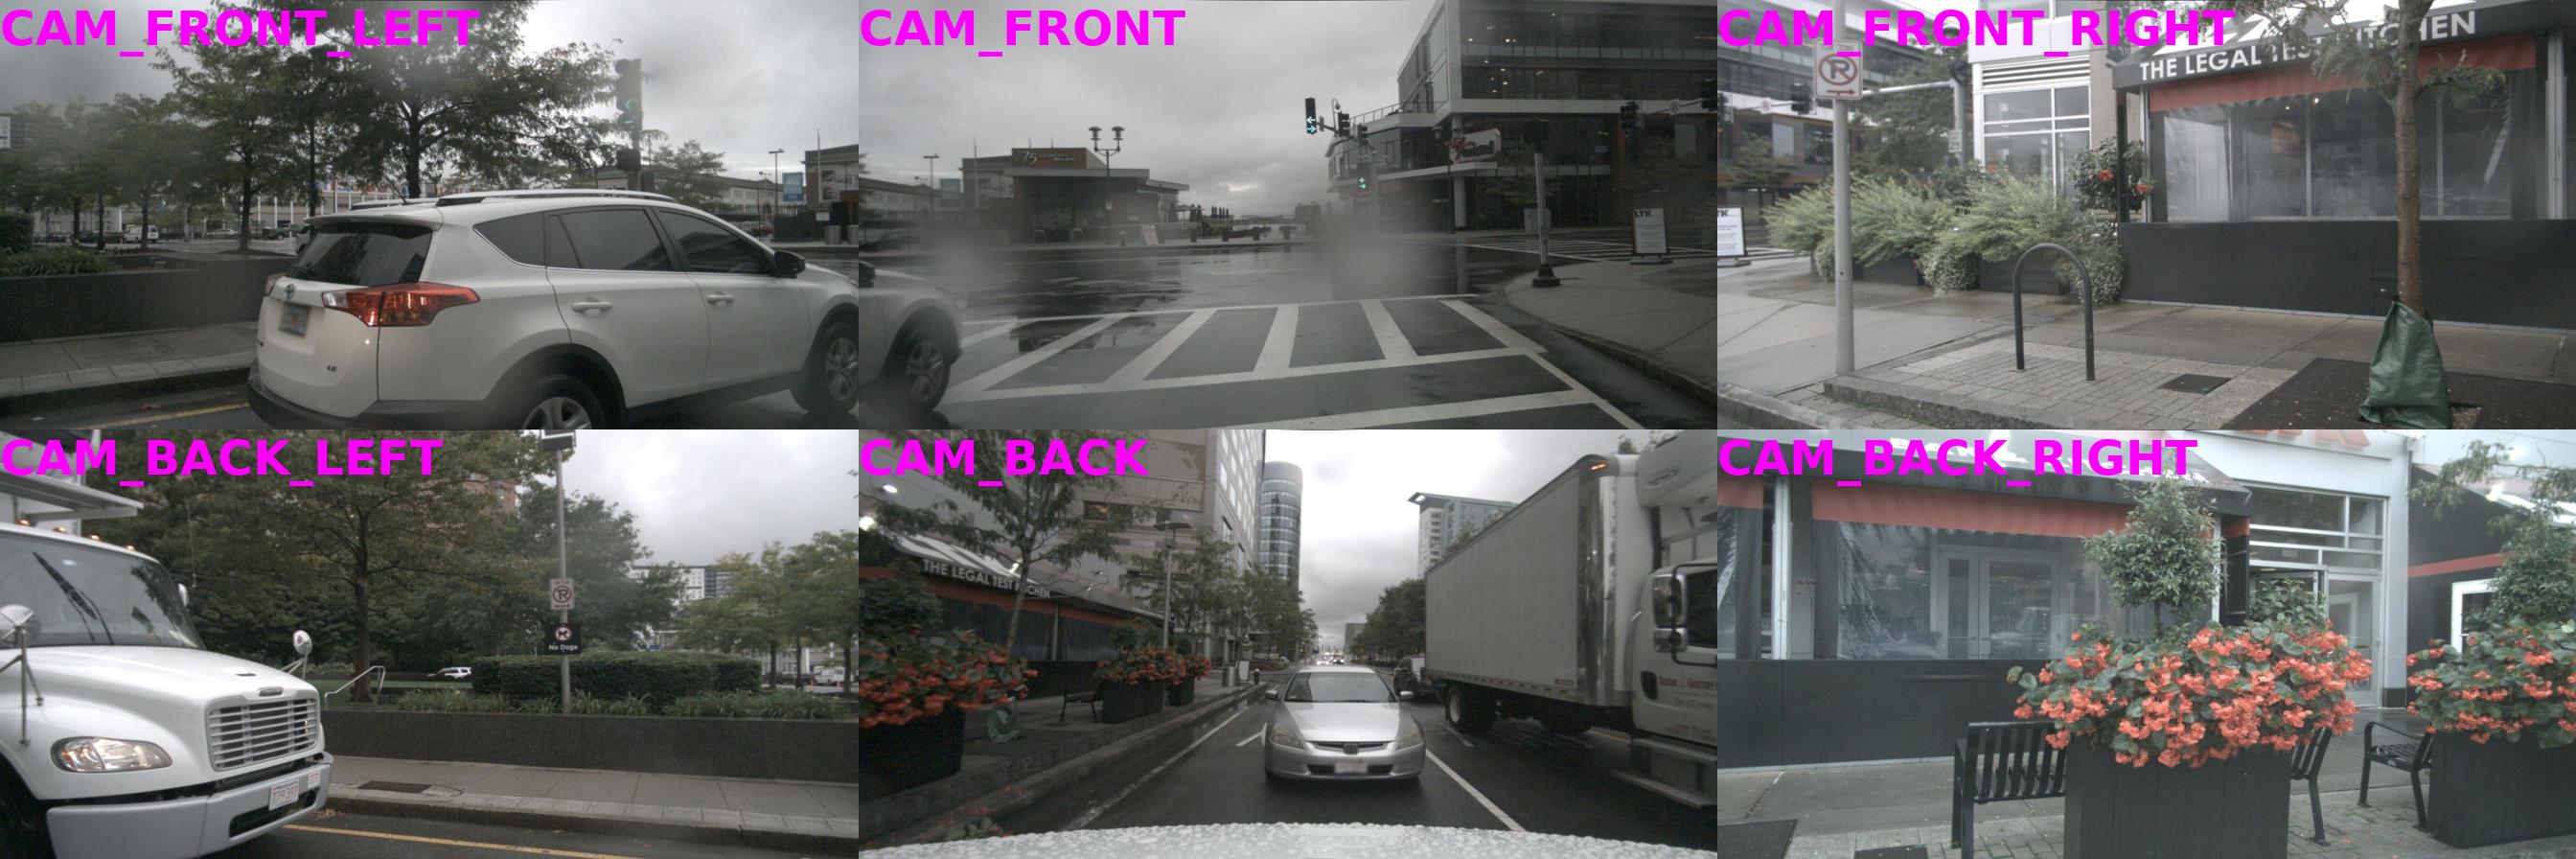 c2c4c3c1
Reading object references: <c2,CAM_FRONT_LEFT,1045.0,596.3> means object c2 in the front-left camera at pixel (1045.0, 596.3) of the original 1600×900 image. Models must produce these references themselves, so wrong coordinates mean the model did not find the object.
Which models are compared?
- InternVL2-2B fine-tuned on the aligned 25k split + 10% LLM-generated pseudo-labels.dkhursen/InternVL2-2b-LoRA-25k_plus_DL-PL-10pct
- Upper bound: our fine-tuned model, tested with ground-truth object markers and their coordinate labels drawn on the images (no retraining). Not deployable; measures the grounding bottleneck.dkhursen/InternVL2-2b-LoRA-25k-drivelm-offline-redcircle-ctag-bkgd
- The base model all our models start from, used as-is.OpenGVLab/InternVL2-2B
- Fine-tuned on the aligned 25k split only.dkhursen/InternVL2-2b-LoRA-25k-drivelm
- Fine-tuned on the full official split: about 12× more data, but not aligned with the test set.dkhursen/InternVL2-2b-LoRA-300k-drivelm
- Released checkpoint of InternVL2-2B, referenced as Mini-InternVL2-2B-DA by OpenGVLab. Fully fine-tuned on the original DriveLM split (~378k questions, ~10× our data); under 0.9% of its training data comes from our test scenes.OpenGVLab/Mini-InternVL2-2B-DA-DriveLM
- General-purpose vision-language model, no driving fine-tuning.llava-hf/llava-v1.6-mistral-7b-hf
- General-purpose vision-language model, no driving fine-tuning.OpenGVLab/llama_adapter_v2_multimodal7b
Score = DriveLM final score (0–1, higher is better) on our test split of 3,340 questions. It combines answer accuracy, a GPT judge, language overlap and object matching. Mini-DA is an external checkpoint released by OpenGVLab; all other fine-tuned models are ours.
Identify all the traffic elements in the front view, categorize them, determine their status, and predict the bounding box around each one. The output should be a list formatted as (c, s, x1, y1, x2, y2), where c represents the category, s denotes the status, and x1, y1, x2, y2 are the offsets of the top-left and bottom-right corners of the box relative to the center point.
What is the moving status of object <c2,CAM_FRONT_LEFT,1045.0,596.3>? Please select the correct answer from the following options: A. Stopped. B. Drive backward. C. Going ahead. D. Turn right.
What object should the ego vehicle notice first when the ego vehicle is getting to the next possible location? What is the state of the object that is first noticed by the ego vehicle and what action should the ego vehicle take? What object should the ego vehicle notice second when the ego vehicle is getting to the next possible location? What is the state of the object perceived by the ego vehicle as second and what action should the ego vehicle take? What object should the ego vehicle notice third? What is the state of the object perceived by the ego vehicle as third and what action should the ego vehicle take?
Is <c1,CAM_BACK,920.0,645.0> a traffic sign or a road barrier?
What actions could the ego vehicle take based on <c1,CAM_BACK,920.0,645.0>? Why take this action and what's the probability?
What actions taken by the ego vehicle can lead to a collision with <c1,CAM_BACK,920.0,645.0>?
In this scenario, what are safe actions to take for the ego vehicle?
Predict the behavior of the ego vehicle. Please select the correct answer from the following options: A. The ego vehicle is slightly steering to the right. The ego vehicle is driving fast. B. The ego vehicle is going straight. The ego vehicle is not moving. C. The ego vehicle is slightly steering to the right. The ego vehicle is driving slowly. D. The ego vehicle is slightly steering to the left. The ego vehicle is driving with normal speed.