MSc thesis, CTU Prague × valeo.ai, 2026
Visual Question Answering for Autonomous Driving
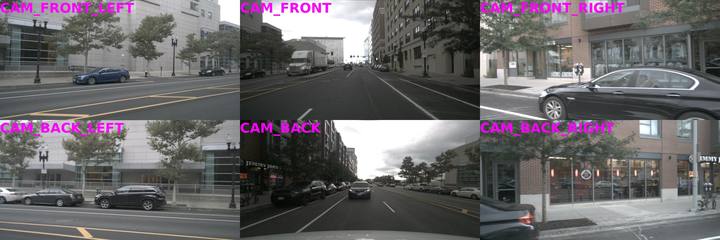
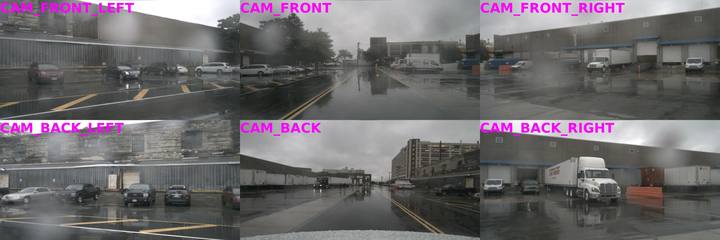
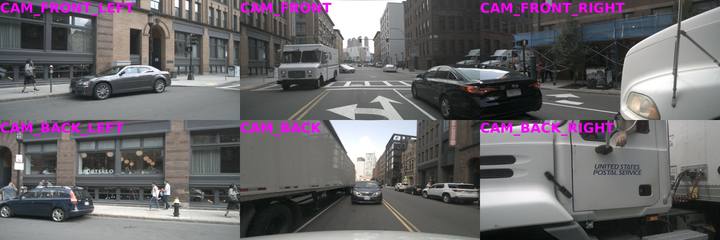
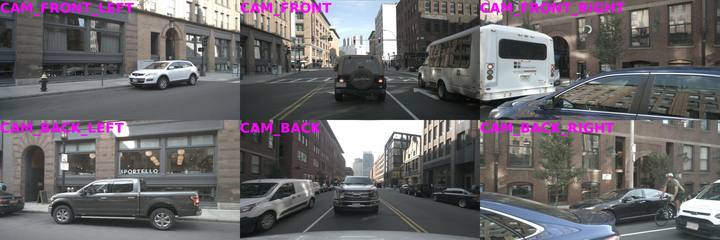
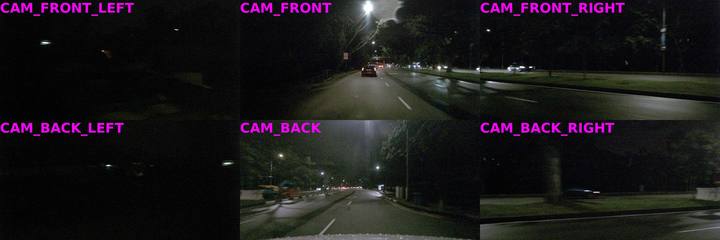
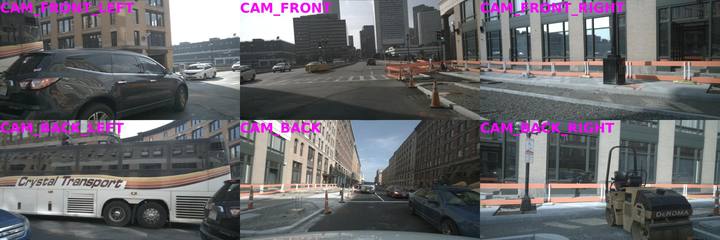
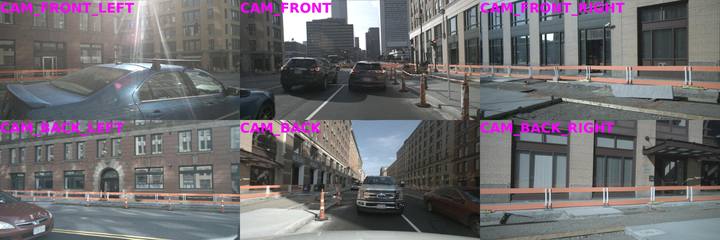
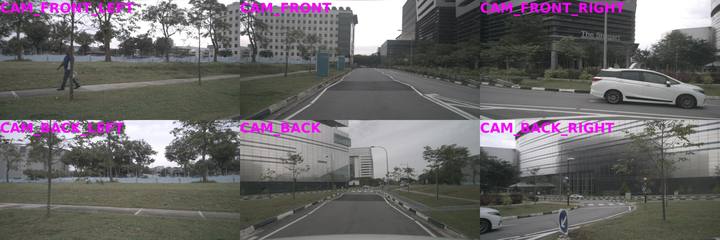
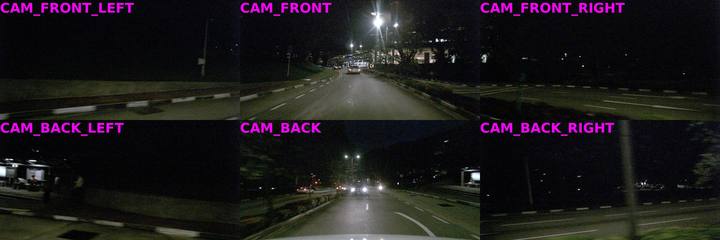
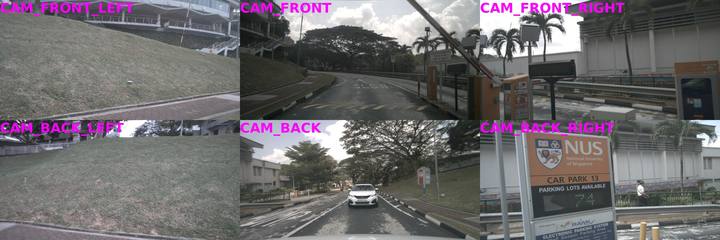
A vision-language model looks at six camera images around a car and answers perception, prediction, planning and behavior questions about the scene. This demo puts its answers next to the ground truth and to baseline models.
Defended at CTU FEE, June 2026 · Read the thesis
Start here: Scene 3 →Headline results
- 0.589Our best model. Fine-tuned InternVL2-2B (2B parameters), close to OpenGVLab's released Mini-DA checkpoint (0.606), which was fully fine-tuned on ~10× more data.
- 0.560 vs 0.493Better data beats more data. 25k training questions aligned with the test distribution beat the 12× larger official split.
- 0.775Grounding is the bottleneck. With ground-truth object markers drawn on the images at test time (oracle, no retraining), the score jumps: models understand the question but struggle to locate objects.
DriveLM final score, 0–1, higher is better, on our test split of 3,340 questions.
Links
Models
- InternVL2-2B fine-tuned on the aligned 25k split + 10% LLM-generated pseudo-labels.dkhursen/InternVL2-2b-LoRA-25k_plus_DL-PL-10pct
- Upper bound: our fine-tuned model, tested with ground-truth object markers and their coordinate labels drawn on the images (no retraining). Not deployable; measures the grounding bottleneck.dkhursen/InternVL2-2b-LoRA-25k-drivelm-offline-redcircle-ctag-bkgd
- The base model all our models start from, used as-is.OpenGVLab/InternVL2-2B
- Fine-tuned on the aligned 25k split only.dkhursen/InternVL2-2b-LoRA-25k-drivelm
- Fine-tuned on the full official split: about 12× more data, but not aligned with the test set.dkhursen/InternVL2-2b-LoRA-300k-drivelm
- Released checkpoint of InternVL2-2B, referenced as Mini-InternVL2-2B-DA by OpenGVLab. Fully fine-tuned on the original DriveLM split (~378k questions, ~10× our data); under 0.9% of its training data comes from our test scenes.OpenGVLab/Mini-InternVL2-2B-DA-DriveLM
- General-purpose vision-language model, no driving fine-tuning.llava-hf/llava-v1.6-mistral-7b-hf
- General-purpose vision-language model, no driving fine-tuning.OpenGVLab/llama_adapter_v2_multimodal7b
Score = DriveLM final score (0–1, higher is better) on our test split of 3,340 questions. It combines answer accuracy, a GPT judge, language overlap and object matching. Mini-DA is an external checkpoint released by OpenGVLab; all other fine-tuned models are ours.
Scenes
26 moments from 22 test scenes recorded in Boston and Singapore. Scenes 12–13, 16–17, 18–19, 20–21 are moments from the same drive.